In this article 7 sections
- 1. Understand token counts first: 4 characters in English, but check Korean directly
- 2. Count input tokens with count_tokens before the call
- 3. Read output tokens from response usage
- 4. Check the pricing period first
- 5. Example calculation: 100,000 input tokens and 20,000 output tokens, including thinking tokens
- 6. List additional charges separately from token calculations
- 7. Checklist
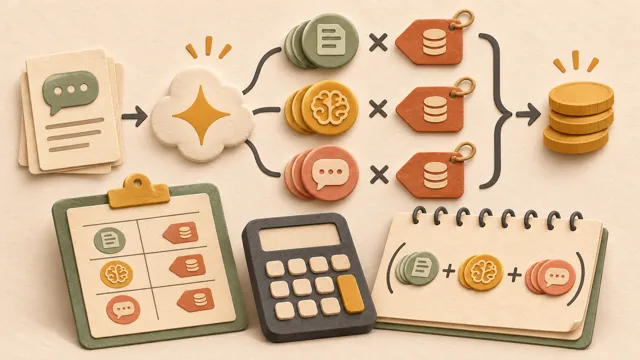
Gemini API costs are calculated for each request by multiplying the input and output tokens by their respective rates. The output also includes thinking tokens. By following the steps below, you can calculate both a single call and monthly usage in the same way. The amounts in this article are calculation examples based on reading the official pricing table as of November 10, 2026, and are not an actual bill.
1. Understand token counts first: 4 characters in English, but check Korean directly
Google’s official documentation explains that one token in Gemini models is approximately 4 characters in English, and that 100 tokens correspond to about 60–80 English words. Because the ratio between character count and token count may differ for Korean, it is safer to check with an actual request rather than estimate from the number of characters.
2. Count input tokens with count_tokens before the call
A count_tokens call returns the total number of tokens in the request input. This value counts only input tokens and does not include output tokens. If you are pasting a long document, it is a good idea to count the tokens once before sending the body.
3. Read output tokens from response usage
The response’s usage values include input (total_input_tokens), output (total_output_tokens), thinking (total_thought_tokens), cached (total_cached_tokens), tool use (total_tool_use_tokens), and total (total_tokens). The pricing table indicates that thinking tokens are included in the output rate, so excluding them from the calculation will underestimate the cost.
4. Check the pricing period first
Even for the same model, the pricing table may include rates for different periods. In the official pricing table, the Gemini 4 Argon Standard rates are $2.00 per 1M input tokens and $10.00 per 1M output tokens, applicable through November 30, 2026. From December 1, the listed rates are $4.00 for input and $20.00 for output. Batch rates increase from $1.00 to $2.00 for input and from $5.00 to $10.00 for output. The amount can double for the same usage depending on the call date.
5. Example calculation: 100,000 input tokens and 20,000 output tokens, including thinking tokens
Using the Standard rates through November 30, the calculation is 0.1M × $2.00 = $0.20 for input and 0.02M × $10.00 = $0.20 for output, for a total of $0.40. Calculating the same request using the Standard rates from December 1 onward gives $0.80. Using Batch rates through November 30, the calculation is $0.10 + $0.10 = $0.20. These are simple calculations in USD and do not account for exchange rates, VAT, regional billing conditions, or free quotas.
6. List additional charges separately from token calculations
The pricing table lists additional items separately from basic token charges, including context caching, Grounding with Google Search, and image output. For models from Gemini 3 onward, Google Search integration includes 5,000 shared requests per month, after which it is listed at $14 per 1,000 requests, and there is also a daily request limit. Image output has rates that differ from token pricing depending on the model. If you use these features, list them on separate lines rather than mixing them into the token calculation.
7. Checklist
① Check the input tokens for each request with count_tokens. ② Read the output tokens and thinking tokens from response usage. ③ Check which pricing period the call date falls into. ④ Determine whether the task requires an immediate result or can be sent as a batch. ⑤ Calculate Search integration, caching, and image output separately if used. ⑥ For monthly costs, do not simply multiply the average number of requests by the cost of one request; calculate based on the distribution of request sizes in the actual logs.
Source materials: Gemini API pricing ↗, Understanding and calculating Gemini API tokens ↗
Related articles: Changes in rates by period were first covered in Notice of the end of the Gemini 3.8 Flash introductory price ↗ and Article confirming the end date of the Gemini 4 Argon introductory price ↗. This article focuses on the calculation process for applying those rates to a single request.
Sources and original article
Read the Korean original on Naver ↗
This article reflects public information available when it was written. Specifications, prices and schedules can change; check the linked official documentation.
This English edition was written and translated with AI assistance, with sources provided. For errors or additional information, please request a correction. Editorial policy

 AI & technology